Minimum Startree version needed for this feature is 0.15
Overview
Query Logger captures a record of the queries your Pinot cluster serves and stores it in a queryable Pinot table calledsystem_query_log. By default it keeps the queries worth investigating, slow ones and failed ones, and you can switch it to capture every query (see What gets captured). Instead of hunting through broker logs, you run ordinary SQL against your own query history to answer questions like:
- Which queries are the slowest or the most expensive right now?
- Which query patterns (templates) dominate load?
- Which queries are scanning too much data, hitting limits, or erroring?
- How has a specific query’s latency or resource usage changed over time?
How it’s enabled
On current StarTree releases, Query Logger is on by default. StarTree provisions thesystem_query_log table and configures the capture pipeline and storage location for you, so you can query the table like any other (via the Query Console or the query API) with no client-side setup.
On older releases it is off by default; contact StarTree Support to enable it for your cluster.
To turn capture off, set querylog.enabled to false (see Configuration). The change applies without restarting brokers, and data already captured stays until retention removes it.
Browse query history in the Data Portal
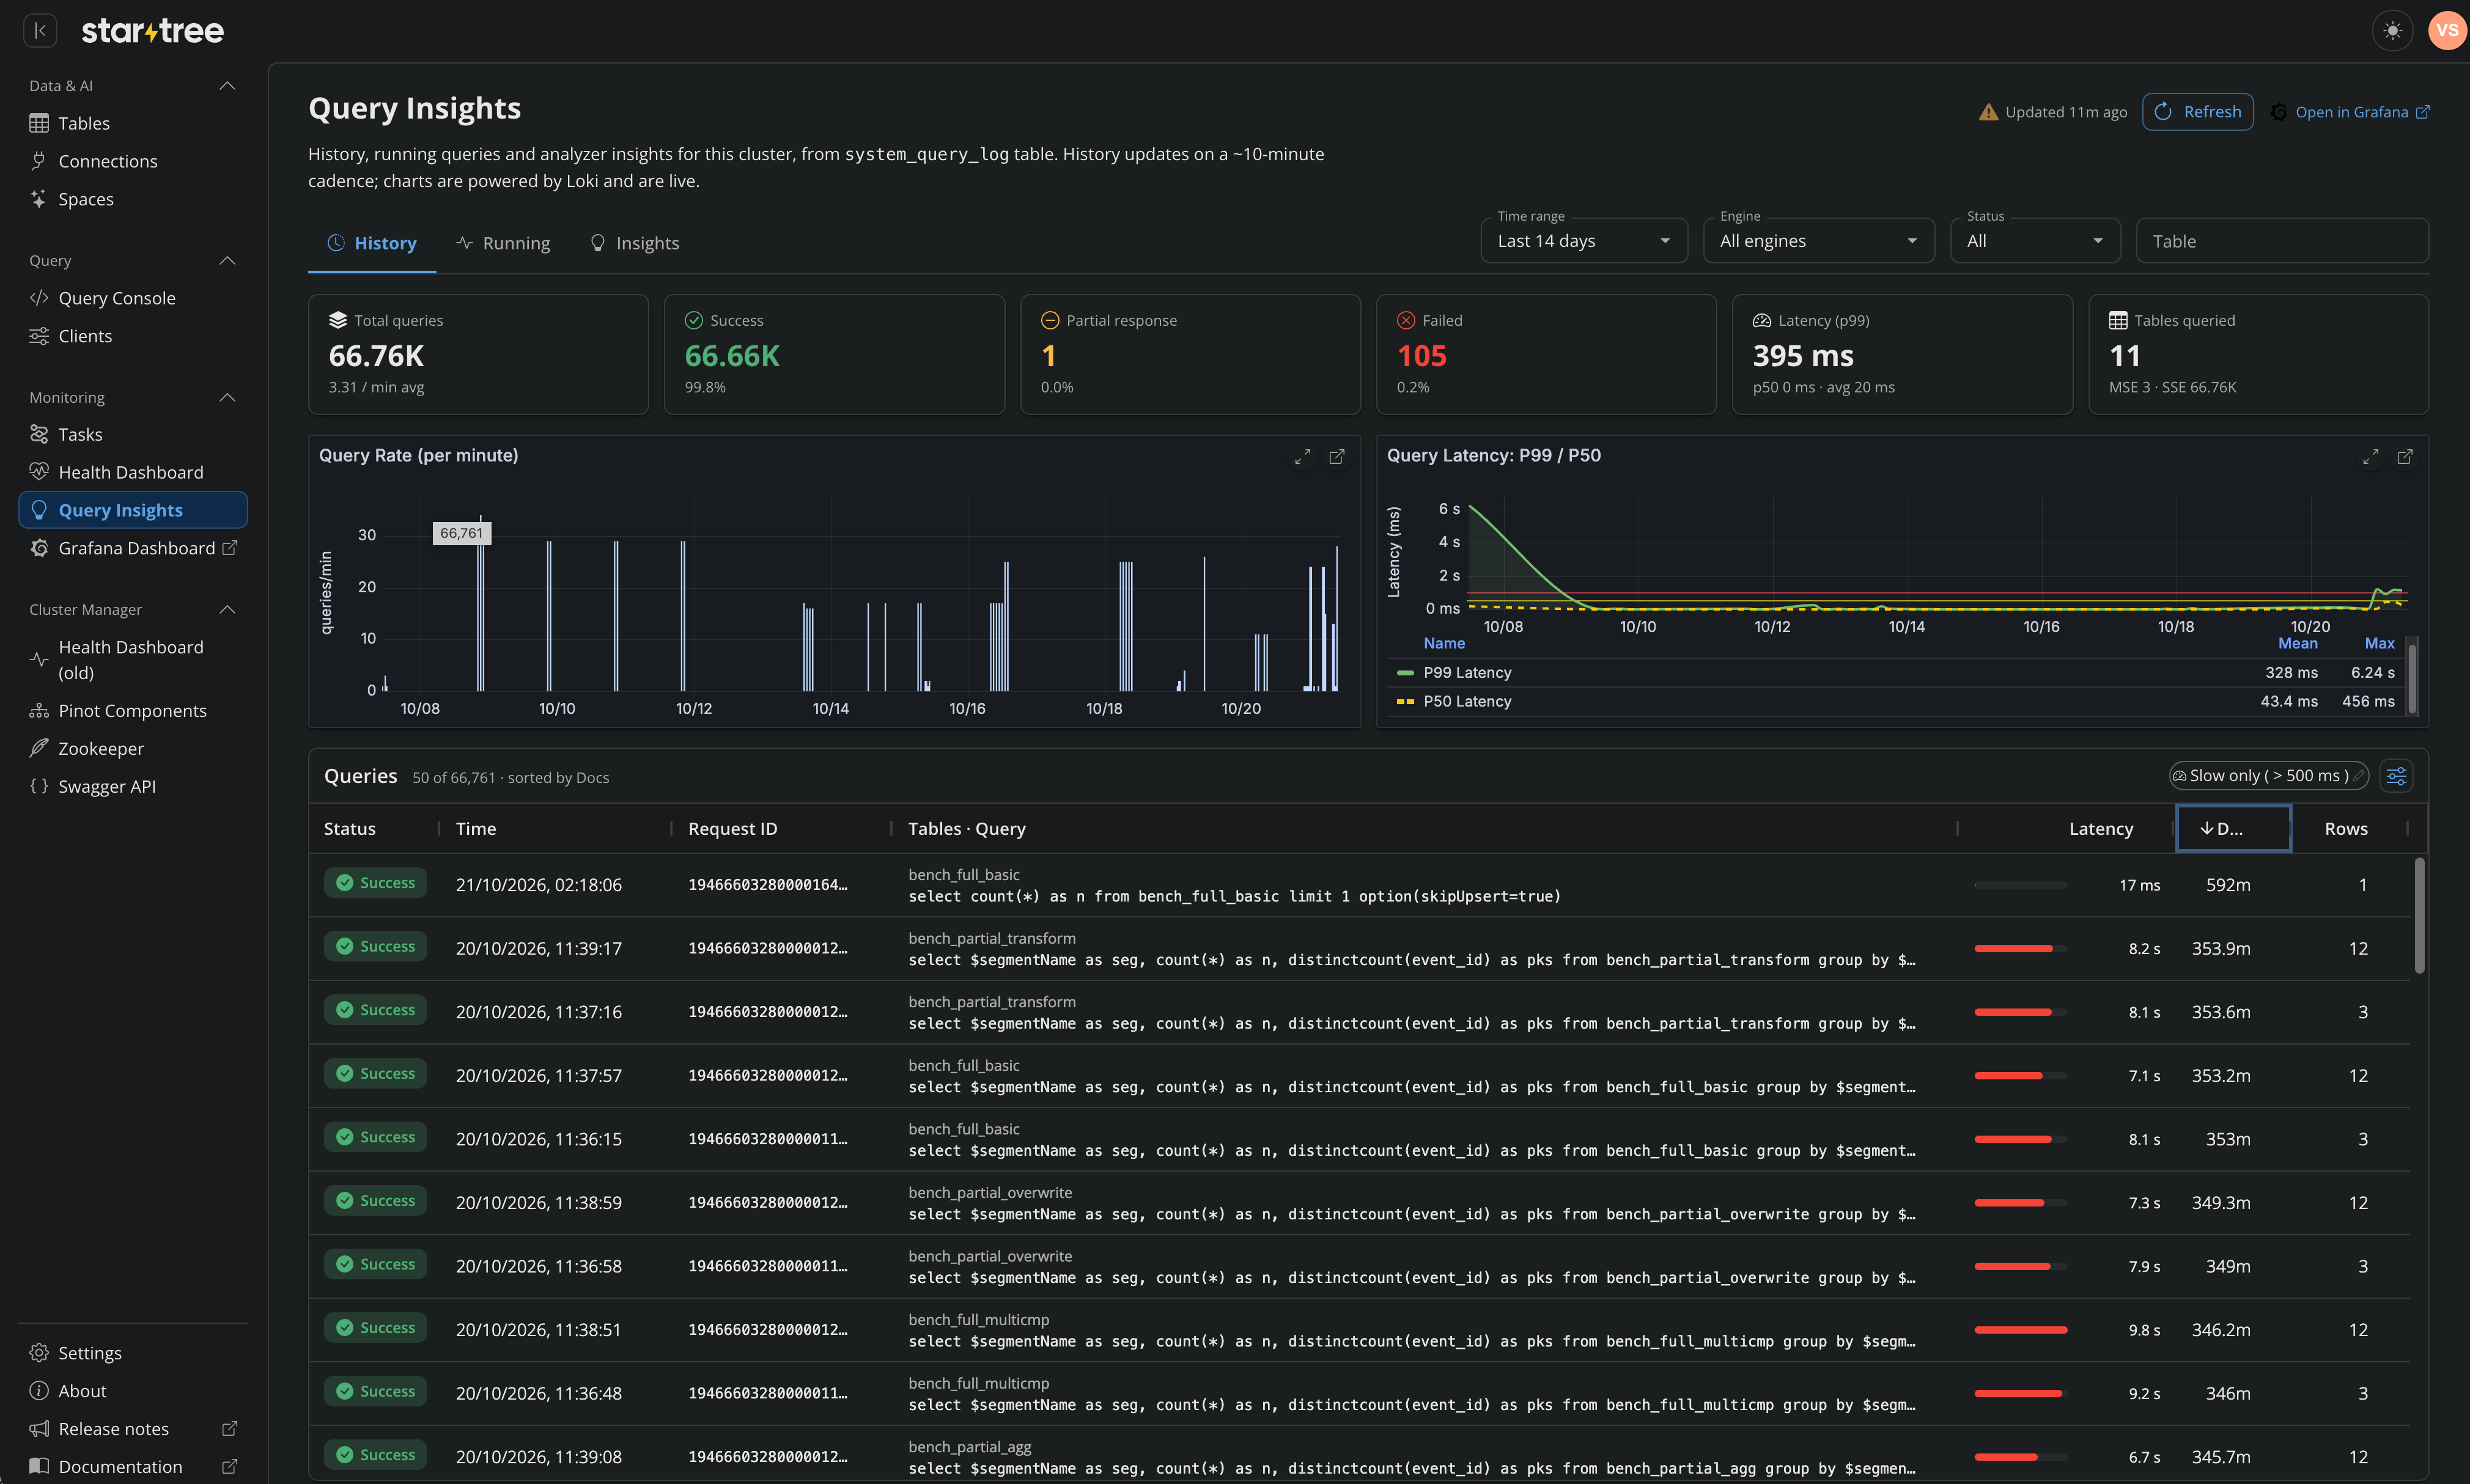
You don’t have to write SQL to look throughsystem_query_log. In the Data Portal, open Monitoring → Query Insights. The History tab reads the same table and shows totals for success, partial-response and failed queries, p99 latency, query-rate and latency charts, and a sortable list of the captured queries. Filter by time range, engine, status or table.
What gets captured
By default, a query is captured when either of these is true:- It took 1 second or longer (
timeUsedMs >= 1000). - It failed with an error.
Clusters that had Query Logger enabled before this default was introduced keep capturing every query after upgrading. Set
querylog.capture.threshold.enabled explicitly to choose either behavior.-
Queries against
system_query_logitself, such as the ones you run while browsing query history. This stops the log from filling up with its own lookups. - StarTree health checks and uptime probes. These are identified by the client that sends them, not by the SQL, so your own queries are never excluded by accident.
-
Queries you opt out individually. Prepend
SET skipQueryLog=true;to a statement you don’t want recorded, such as a high-frequency health check of your own:This only affects logging. The query still runs and returns results normally.
Configuration
Query Logger settings are cluster configs. Change them with the controller’s cluster-config API:Capture settings
These apply to new queries without restarting brokers.The table setting is an allowlist only. There is currently no setting to capture every table except a few.
Table settings
These control thesystem_query_log table itself.
Set the tenants before the table is created if your cluster has no
DefaultTenant, or if you want query history kept off the servers that handle production traffic.
The data: key fields
The table has ~70 columns. The ones you’ll use most, grouped by purpose: Identity & context
Timing & result
Data scanned (why a query is expensive)
Resource usage
Limit / safety flags (booleans):
numGroupsLimitReached, groupsTrimmed, maxRowsInJoinReached, maxRowsInWindowReached, maxRowsInDistinctReached — these tell you a query hit a guardrail and may have returned trimmed/partial data.
Deep diagnostics: stageStats (JSON, multi-stage per-operator stats), serverStats, traceInfo, responseMetadataJson — for detailed drill-down.
* queryHash is populated only when query fingerprinting is enabled for your cluster; otherwise it may be empty. Ask StarTree Ops if you plan to rely on it.
Sample queries
All examples filter to the last 24 hours using logTimestampMs. Adjust the window as needed. Always keep a time filter on these queries (see Limitations & caveats).
Top 10 slowest queries (last 24h)
How the data is kept tidy
You don’t manage any of this — it’s handled automatically — but it’s useful to know:- Automatic segment compaction. The pipeline lands data as many small segments (one every few minutes per broker). A background merge/rollup job runs on a schedule and compacts those small segments into fewer, larger ones, keeping the total segment count bounded as the table grows. No action is required on your part.
- Automatic retention. Data older than the configured retention window is dropped automatically, so the table stays within its storage budget.
Limitations & caveats
⚠️ It consumes storage on your cluster. system_query_log is a real Pinot table — its segments occupy disk on your servers. StarTree keeps it bounded with an automatic retention window (older data is dropped, 7 days by default) and a storage quota (300 GiB by default), and the background merge job (above) keeps the segment count in check, so the footprint stays finite. When the table reaches its quota, newly captured queries stop landing until retention frees space; existing history is not deleted early. High-QPS clusters, or clusters that capture every query, generate more log data; see Table settings and talk to StarTree Support if you need a longer window or expect large volume.
⚠️ Your analysis queries run on the same cluster. Queries againstsystem_query_logexecute on the same brokers and servers serving your production traffic and compete for the same resources. Always filter bylogTimestampMsto a bounded window and avoid unboundedSELECT *scans, so debugging doesn’t add load to an already-busy cluster.
- Near-real-time, not instant. Logged queries appear after background segment generation runs — expect a short delay (roughly 10–15 minutes) before a just-executed query is queryable. It’s for analysis and debugging, not live monitoring.
- Long fields are truncated.
query(4096 characters by default, seequerylog.max.query.length),exceptions,serverStats, andtraceInfohave maximum lengths; extremely large values are cut off. - One row per captured query. By default only slow and failed queries are stored (see What gets captured), so counts from this table are not total query volume unless capture is set to every query.
- Best-effort capture. Under extreme broker load, or during an error storm where many queries qualify at once, some records may be dropped rather than slow down query serving.